Competitor Database: Build the System That Scales Intelligence
A competitor database sounds simple until you try to build one that actually works. Most teams start with good intentions-a spreadsheet, a Notion page, maybe a Slack channel where someone shares competitor sightings. Six months later, it's chaos: outdated entries, duplicate records, no one knows what's real anymore, and the executive asking "who are we up against?" gets three different answers depending on who's in the room. The gap between "tracking competitors" and "having usable intelligence" is where most organizations die quietly, outmaneuvered by rivals who solved the same problem better.
The hard truth: a competitor database is not a list. It's a decision-support system. If it doesn't help you decide faster and smarter than your competitors, it's decorative. This article shows you how to build a competitor database that scales with your business, stays current without heroic manual effort, and actually drives strategy instead of gathering dust.
What a Competitor Database Actually Does
A competitor database organizes every entity competing for your customer's attention, budget, or loyalty into a structured, queryable view. That includes direct competitors (same solution, same market), indirect competitors (different solution, same job-to-be-done), and emerging threats (adjacent categories moving into yours).
The system must answer three questions instantly:
- Who are we up against? Complete roster, segmented by threat level, category, and strategic posture.
- What are they doing? Product changes, pricing moves, messaging shifts, funding events, leadership changes.
- What does that mean for us? Implications, vulnerabilities to exploit, attacks to defend against.
If your database can't answer all three, it's incomplete.
The Architecture of Usable Intelligence
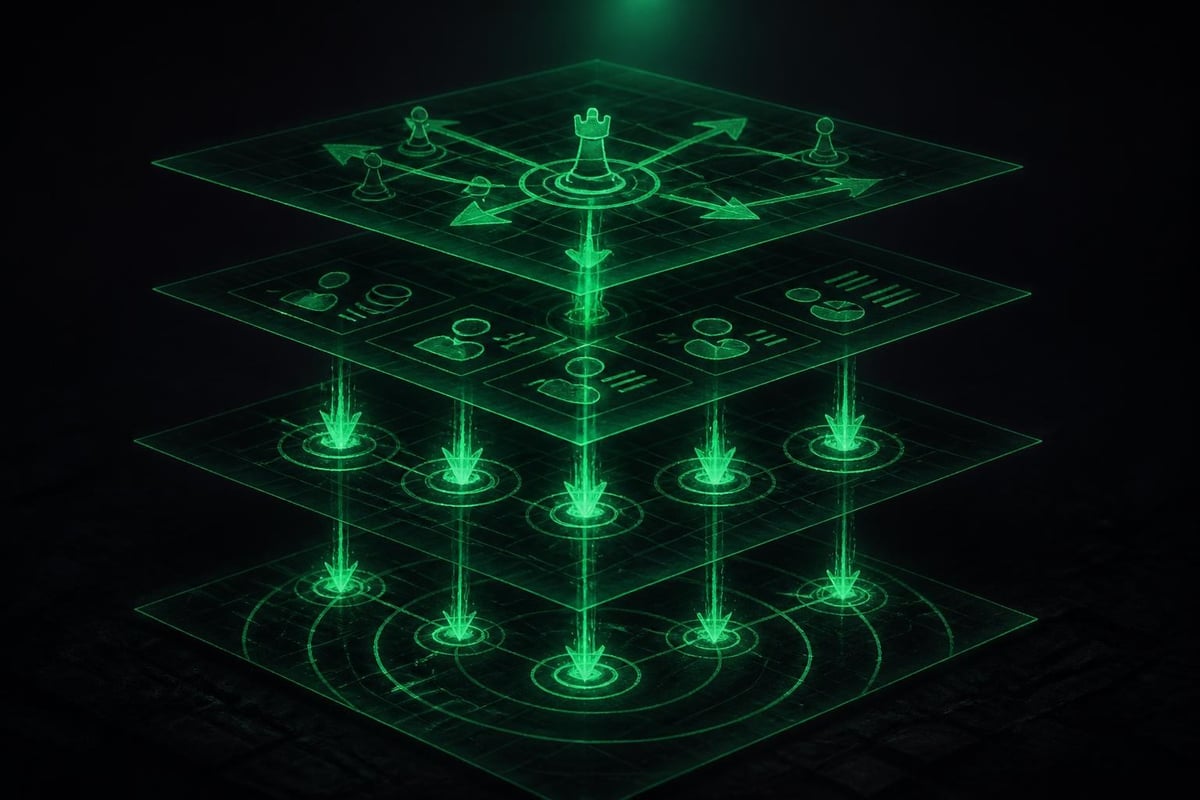
A working competitor database has four layers:
Discovery layer: How new competitors enter the system. Manual entry doesn't scale; you need automated signals (web scraping, news feeds, social listening, funding databases) plus human curation to filter noise. BrandScout’s free competitor discovery tool solves this by surfacing hidden and rising competitors automatically, then organizing them in a living view that updates as new intelligence arrives.
Entity resolution layer: Deduplicates records and links related entities. Company name variations, acquired brands, renamed products-without canonicalization, you get fragmented data and bad decisions. Research on scalable entity resolution architectures offers technical guidance for building reliable linkage at scale.
Enrichment layer: Appends structured metadata to each competitor (category, size, funding stage, tech stack, key personnel, strategic posture). This transforms a flat list into a multi-dimensional map you can slice by any attribute.
Analysis layer: Connects competitor data to frameworks (SWOT, Five Forces, Ansoff) and outputs actionable strategy. Most databases stop at enrichment and leave teams staring at dashboards, paralyzed. The analysis layer is where intelligence becomes a play.
Building the Schema That Scales
Your data model determines what questions you can answer later. Build it too narrow, and you'll outgrow it in six months. Build it too complex, and no one will maintain it.
Core Entities and Relationships
Start with three tables:
| Entity | Key Fields | Purpose |
|---|---|---|
| Competitors | Name, category, founded date, HQ location, employee count, funding stage | Canonical record for each competitor |
| Products | Product name, launch date, pricing model, target segment, key features | What they sell and to whom |
| Events | Event type (funding, launch, hire, pivot), date, source, impact score | Timeline of competitive moves |
Link them with foreign keys: each Product belongs to a Competitor; each Event references a Competitor or Product. This relational structure lets you query "show me all SaaS competitors who raised Series B in 2025 and launched a freemium tier" in seconds.
Add a Sources table to track where intelligence came from (URL, date scraped, reliability score). Data governance frameworks that map GDPR interplay become critical when you're collecting public-web signals across jurisdictions. Document provenance or risk compliance exposure.
Metadata Taxonomy
Enrich each competitor with categorical tags:
- Strategic posture: Leader, challenger, niche specialist, new entrant
- Business model: SaaS, marketplace, transaction, advertising
- Target segment: SMB, mid-market, enterprise, prosumer
- Threat level: Critical (direct overlap, strong), moderate, watching
Consistent taxonomy enables filtering and pattern recognition. "Show me all enterprise-focused challengers with recent funding" becomes a two-click query instead of a manual review.
Privacy and Legal Boundaries
Competitor databases often include data scraped from public sources, which triggers legal and ethical questions. The FTC’s annual reporting and strategic guidance provides context on how competition authorities view information-gathering practices. Stay inside fair use, respect robots.txt, and understand the legal basis for processing under GDPR if you're collecting behavioral or personal data.
Don't store more than you need. If you're tracking a competitor's pricing, you don't need the names of their sales reps unless there's a strategic reason.
Keeping the Database Current Without Heroic Effort
Static databases rot fast. A competitor who looked irrelevant in January can be your biggest threat by June. The question is how to stay current without hiring someone full-time to refresh spreadsheets.
Automated Signal Ingestion
Set up feeds that push updates into your database automatically:
- News APIs for mentions of competitor names
- Job board scrapers to detect hiring spikes (signal of expansion or new product development)
- Funding trackers (Crunchbase, PitchBook) for capital events
- Product Hunt, G2, Capterra for new launches and user sentiment
- GitHub activity if competitors are open-source or developer-focused
Practical data-modeling patterns like Microsoft’s Unified Data Model offer a scalable schema approach for integrating heterogeneous signals into one governed structure.
Run nightly jobs to deduplicate, score relevance, and surface high-priority changes. Low-impact signals (blog posts, minor UI tweaks) go into the log; high-impact signals (pricing changes, executive departures, new market entry) trigger alerts.
Human-in-the-Loop Curation
Automation finds signals; humans decide what they mean. Build a weekly triage workflow:
- Review flagged high-priority events
- Validate accuracy (is this real or a rumor?)
- Update threat scores and strategic posture
- Flag implications for your roadmap or positioning
This takes 60-90 minutes per week instead of 8 hours of manual research. The leverage is enormous.
Quality and Deduplication
AI-driven approaches to master data management improve data quality through automated deduplication and enrichment. When two scrapers pull the same competitor under slightly different names, entity resolution merges them without manual reconciliation.
Set quality thresholds: any competitor record missing >30% of core fields gets flagged for review. Incomplete data is worse than no data because it gives false confidence.
Turning Data Into Decisions
A database full of accurate competitor records is useless if no one knows what to do with it. The analysis layer connects intelligence to action.
Segmentation and Prioritization
Not all competitors deserve equal attention. Segment by:
- Direct revenue threat: Do they compete for the same deals?
- Strategic position: Are they moving into your stronghold or away from it?
- Momentum: Recent funding, product velocity, market share trends
Focus 80% of analytical effort on the top 20% of threats. The rest go into "watching" status with automated monitoring.
Framework Integration
Run your competitor data through proven strategic frameworks:
- Porter's Five Forces to map bargaining power, threat of substitutes, competitive rivalry
- SWOT to identify their vulnerabilities and your attack surface
- Ansoff Matrix to predict their next growth move (market penetration, product development, market expansion, diversification)
BrandScout's premium competitive analysis runs these frameworks automatically and outputs 90-day action plans grounded in real competitive data, solving the "I have a list but don't know what to do with it" problem.
Battlecard Generation
Sales teams need competitor intelligence compressed into decision aids: one-page battlecards that show positioning, strengths/weaknesses, objection handling, and win themes. Pull directly from your competitor database:
- Positioning: How they describe themselves vs. how you should describe them
- Weaknesses: Where they're vulnerable (pricing, support, feature gaps, churn)
- Proof points: Wins you've had against them, customer quotes, comparative data
Update battlecards quarterly or when a competitor makes a major move. Outdated battlecards lose deals.
Governance, Access, and Cross-Functional Use
A competitor database serves multiple teams. Product wants to know feature gaps. Marketing wants messaging angles. Sales wants objection handling. Strategy wants market maps. Each needs different views of the same underlying data.
Role-Based Access
Not everyone should see everything. Sensitive intelligence (pricing details, customer defection data, legal risks) gets restricted access. Public data (product features, press releases, team size) is open to all.
Define access tiers:
- Public tier: Basic competitor profiles, publicly stated positioning
- Internal tier: Enriched data, SWOT analysis, threat scores
- Leadership tier: Financial estimates, strategic vulnerabilities, attack plans
Cross-Functional Workflows
Integrate your competitor database into existing workflows:
- Product planning: Query competitors by feature set to find gaps
- Pricing reviews: Compare pricing models and positioning tiers
- Campaign planning: Identify competitors' weak messaging angles
- Sales enablement: Auto-generate battlecards from database fields
The database becomes infrastructure, not a side project.
Synthetic Data for Testing and Sharing
When sharing competitive intelligence externally (partners, investors, advisors), consider synthetic data approaches outlined by the World Economic Forum. Synthetic datasets preserve structure and patterns while removing real competitor identities, reducing legal and privacy risk.
Common Failures and How to Avoid Them
Most competitor databases fail predictably. Here's how to sidestep the traps.
Failure Mode 1: No Single Source of Truth
Three people maintain three different lists. When leadership asks "who are our top competitors?" the room argues. Fix: Designate one canonical system. Sunset all shadow databases. Enforce it.
Failure Mode 2: Too Much Manual Effort
Someone spends 10 hours a week updating records by hand. They leave, the database dies. Fix: Automate signal ingestion. Human effort should go into curation and analysis, not data entry.
Failure Mode 3: Data Without Analysis
You have 200 competitor profiles and no idea which five matter most. Fix: Add threat scoring, segmentation, and framework integration. Raw data is not intelligence.
Failure Mode 4: Ignoring Emerging Threats
You track the obvious incumbents and miss the startup that steals your market in 18 months. Fix: Automated discovery that surfaces rising competitors based on funding, hiring, and market signals-not just brand recognition.
Failure Mode 5: Privacy or Legal Exposure
You scrape competitor sites aggressively, ignore robots.txt, store personal data without legal basis, and get a cease-and-desist or GDPR complaint. Fix: Ethical web scraping frameworks and documented data governance. Consult legal before deploying any automated collection at scale.
Scaling Across Multiple Brands or Clients
Agencies, incubators, accelerators, and multi-brand companies face a compounding problem: running competitive intelligence for 10 brands means 10x the discovery, tracking, and analysis work. Most teams either do shallow research across all brands or deep research on one and neglect the rest.
The solution is multi-tenant architecture: one system, multiple isolated competitive landscapes. Each brand gets its own competitor roster, analysis, and strategy, but you manage them all from a single interface. This eliminates repeated work and keeps every brand's intelligence current without multiplying headcount.
BrandScout's multi-brand offering runs the full discovery-to-strategy workflow across separate competitive landscapes from one account, solving the scale-and-repetition problem of redoing CI for each brand or client.
The ROI of a Well-Built Competitor Database
Quantify the value:
- Faster decisions: Executives get answers in minutes instead of waiting days for someone to research and compile a memo.
- Better positioning: Marketing and sales know exactly where you win and lose, so messaging hits harder.
- Reduced risk: Early warning on competitive moves (pricing cuts, new entrants, feature launches) gives you time to respond instead of scrambling.
- Higher win rates: Sales armed with current battlecards and competitive intelligence close more deals against named competitors.
One enterprise SaaS company tracked a 12% increase in win rate after rolling out structured competitor battlecards pulled from their database. Another reduced time-to-insight on new competitors from two weeks to two hours. The ROI isn't speculative-it's measurable.
A competitor database is the difference between reacting to threats after they've already hurt you and seeing them in time to counter or exploit them. Build it as a system-discovery, resolution, enrichment, analysis-or accept that your rivals are operating with better intelligence. BrandScout turns scattered market signals into structured intelligence, so you can map your competitive landscape, run strategic analysis, and act with confidence instead of guesswork.